Generative AI Model Fine-Tuning: A Practical Guide
A general-purpose model can write a polished email, summarize a report, or explain a tricky idea. Yet when you give it the same specialized task every day, small inconsistencies start to matter: the tone shifts, the format changes, or it misses a rule your team follows.
Fine-tuning can help make a model more consistent at a specific job. It takes examples of the behavior you want and uses them to adjust a pretrained model. That can be useful—but only when the examples address a real, repeatable problem. Fine-tuning isn’t a shortcut for every weak answer, and it won’t automatically make a model more knowledgeable.
Table of Contents
- What fine-tuning changes
- Fine-tuning, prompting, and retrieval
- When fine-tuning is worth considering
- Choosing a fine-tuning method
- Building a useful training dataset
- Training, evaluation, and iteration
- Common fine-tuning mistakes
- Costs, privacy, and ongoing maintenance
- A practical takeaway
What Fine-Tuning Changes
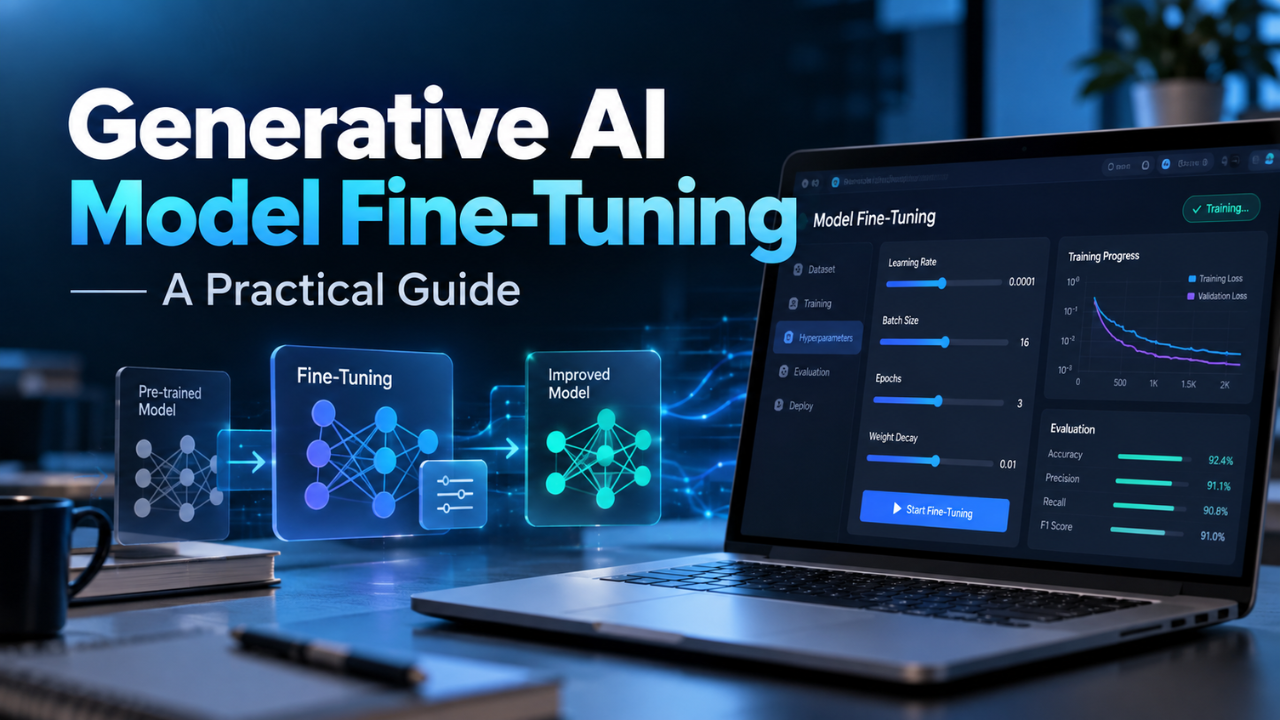
A generative AI model begins with patterns learned during pretraining. Fine-tuning continues that learning with a smaller, more targeted set of examples. In supervised fine-tuning, for instance, examples show the model an input and the kind of output that should follow. The model’s parameters are then adjusted to make those responses more likely.
That difference can sound abstract, so picture a customer-support team. Its base model can answer general questions, but the company wants replies to follow a particular structure: acknowledge the issue, explain the next step, and avoid promising a refund before a case is reviewed. Fine-tuning examples can teach that recurring response pattern.
The model isn’t simply memorizing a new instruction sheet. Its behavior is being shaped by training examples, which is why those examples need to be consistent and representative. Fine-tuning can improve performance on a defined task, but it cannot guarantee a correct answer every time. The model still needs clear instructions, sensible safeguards, and testing against real requests.
Fine-Tuning, Prompting, and Retrieval
Before changing a model, try improving the prompt. A clear instruction, a relevant example, and a defined output format can solve many problems without a training run. If a model gives poor results only because the request is vague, fine-tuning may just teach it to handle that vague request more consistently.
Retrieval-augmented generation, or RAG, tackles a different need. It retrieves relevant information from documents or a knowledge source and includes that context when the model generates an answer. That makes it useful when answers depend on facts that change, such as current prices, policies, product details, or internal procedures.
Fine-tuning is usually a better fit for repeatable behavior: a preferred tone, a response format, or a task with recurring patterns. RAG is usually a better fit for supplying specific information that may be updated. The two can work together: retrieve the latest product details, then use a fine-tuned model to explain them in a consistent support style.
A practical rule: if the model needs different facts, improve its access to information. If it needs to perform the same task more reliably, consider tuning its behavior.
When Fine-Tuning Is Worth Considering
Fine-tuning makes the most sense when you can point to a repeated failure. Perhaps a model classifies incoming requests inconsistently, extracts fields in different formats, or keeps ignoring an important writing convention. You should be able to describe the desired change in plain language and recognize it in a good example.
It can also help when long prompts contain many examples and rules that appear in nearly every request. Moving some recurring guidance into a tuned model may simplify the prompt, though the actual effect on cost and response quality depends on the model, provider, and workload. Google recommends starting with prompt design, then considering tuning when task-specific improvements are still needed. It also emphasizes using high-quality examples that reflect the prompts and context the model will encounter in production.
By contrast, fine-tuning is a poor first choice when the problem is unclear, happens only occasionally, or depends on a stream of changing facts. If you can’t explain what “better” means—or can’t gather examples that demonstrate it—you won’t have a reliable way to tell whether the training worked.
Choosing a Fine-Tuning Method
The simplest route to understand is supervised fine-tuning (SFT). You provide examples of inputs and desired outputs, and the model learns patterns from them. SFT suits tasks where a good response can be demonstrated clearly, such as rewriting a message into a set format, sorting support tickets, or extracting information from a form.
Full fine-tuning updates all of the model’s parameters. That can be useful for demanding adaptations, but it generally takes more computing resources and requires more care to train and deploy. For many projects, a parameter-efficient method is more practical.
LoRA, short for Low-Rank Adaptation, is one common option. It keeps the original model weights frozen and trains smaller added matrices that capture task-specific updates. That can reduce the number of parameters that need training, while letting teams maintain separate lightweight adaptations for different tasks. The best method depends on the model and training setup, so check what your platform supports before planning a pipeline.
Some tasks involve preferences rather than a single correct answer. A support reply might be accurate in two different ways, while one sounds more helpful and less abrupt. Preference-based tuning uses comparisons or feedback to teach a model which responses people prefer. It’s a distinct approach, and it works best when reviewers can apply the same criteria consistently.
Building a Useful Training Dataset
A dataset is not useful just because it is large. Each example should show a realistic input and a response you would actually want the model to produce. If a customer asks, “Can I change my delivery address?” a good example should reflect the company’s actual policy, tone, and escalation process—not a generic answer that sounds plausible.
Include variety. If every example uses the same wording, the model may learn to handle that wording rather than the task. Use natural differences in phrasing, short and detailed requests, common edge cases, and examples where the right response is to ask a clarifying question. Keep the desired outputs consistent in the qualities that matter, while allowing normal variation in wording.
Clean the data before training. Remove duplicate examples, fix contradictory answers, and check for details that don’t belong in a training set, such as private customer information or outdated policies. Be careful with examples that were copied from production: an impressive-looking dataset can still teach the wrong behavior if the responses contain mistakes.
Set aside examples for evaluation before training begins. Those held-back examples let you check how the tuned model handles requests it hasn’t trained on. If you evaluate only on training data, the model may look excellent simply because it has learned those examples too closely. The format and validation rules vary between providers, so follow the requirements for the model you choose.
Training, Evaluation, and Iteration
Start with a baseline: run the untuned model on a small, representative set of real requests. Save the prompts and outputs. That gives you a fair comparison later, instead of relying on a vague impression that the tuned version “feels better.”
Then train a first version and test it on the held-back set. Use criteria that match the job. For classification, check whether cases land in the right categories. For extraction, check whether the required fields are present and correct. For writing, have reviewers score whether the response follows the requested tone, structure, and policy. A single overall score can hide a problem that appears only in an important type of request.
Try a small pilot before making the model part of a live workflow. Compare its outputs against the baseline, inspect failures, and ask whether the improvement matters enough to justify the extra complexity. If results are weak, look at the examples first. Missing cases, inconsistent labels, or a mismatch between training and real prompts can limit performance.
Keep the test set fixed while comparing versions. When you revise the dataset, add a separate batch of new examples for another check. Otherwise, you may gradually tune the model to the very questions you use to judge it. In practice, dataset review and evaluation often take more attention than the training run itself.
Common Fine-Tuning Mistakes
One common mistake is trying to fix a knowledge problem with behavioral training. A model might learn to respond in a polished, confident voice while still lacking access to the latest support policy. If the answer depends on information that changes, provide a reliable source of current information instead of expecting the model’s trained behavior to keep facts up to date.
Another mistake is adding more data before understanding the failures. If a model keeps omitting one required field, inspect examples where it omits the field and examples where it gets it right. A targeted correction may help more than a large batch of loosely related training records.
Overfitting is another risk. A model that performs well on familiar examples may struggle with natural variations in user wording. That’s why held-back evaluation data and a small real-world pilot matter. Also, don’t assume that a tuned model will obey every instruction. Continue to test boundaries, refusals, and unusual requests relevant to the application.
Costs, Privacy, and Ongoing Maintenance
Fine-tuning has costs beyond the initial training run. You may need time to prepare examples, review outputs, monitor performance, and update the model when the task changes. Depending on the platform, there may also be costs for hosting or running the tuned version. Check the pricing and deployment details for your chosen provider rather than assuming tuning will lower total costs.
Treat training examples as part of your data governance. Decide who can access them, remove information that isn’t needed, and confirm that you have permission to use the material for training. If examples reflect a policy or process, assign someone to check whether they remain accurate as that policy changes.
Keep track of which model version is being used and what changed between versions. If a new version starts mishandling a key request type, you’ll want to trace the change and switch back while you investigate. A tuned model needs the same practical oversight as any other system used to answer real people.
A Practical Takeaway
Generative AI model fine-tuning is most useful when a model needs to perform a specific, recurring task more consistently. Start with the prompt, identify a measurable failure, and prepare examples that show the behavior you want. Then compare the tuned model with a baseline on realistic requests.
A good fine-tuning project isn’t defined by how much data it uses or how complicated the training setup looks. It’s defined by whether the model handles a real job better—and keeps doing so when people ask in their own words.