Retrieval Augmented Generation (RAG): A Practical Guide
Ask a chatbot about your company’s refund policy, and it may give you a perfectly reasonable answer. The trouble starts when that answer describes a policy your company has never used.
That gap explains the appeal of retrieval augmented generation (RAG). It gives a language model relevant information to consult before responding, such as product manuals, support articles, or internal documents.
Think of it as giving someone the right reference material before asking for an explanation. The idea is simple. Getting the right information into the answer takes more care.
Table of Contents
- What RAG Actually Does
- From a Question to a Grounded Answer
- Why the Search Step Matters So Much
- Good Answers Start With Useful Documents
- Where RAG Earns Its Place
- RAG and Fine-Tuning Solve Different Problems
- What Can Still Go Wrong
- How to Tell Whether It’s Working
- Start Small and Keep the Sources Current
What RAG Actually Does
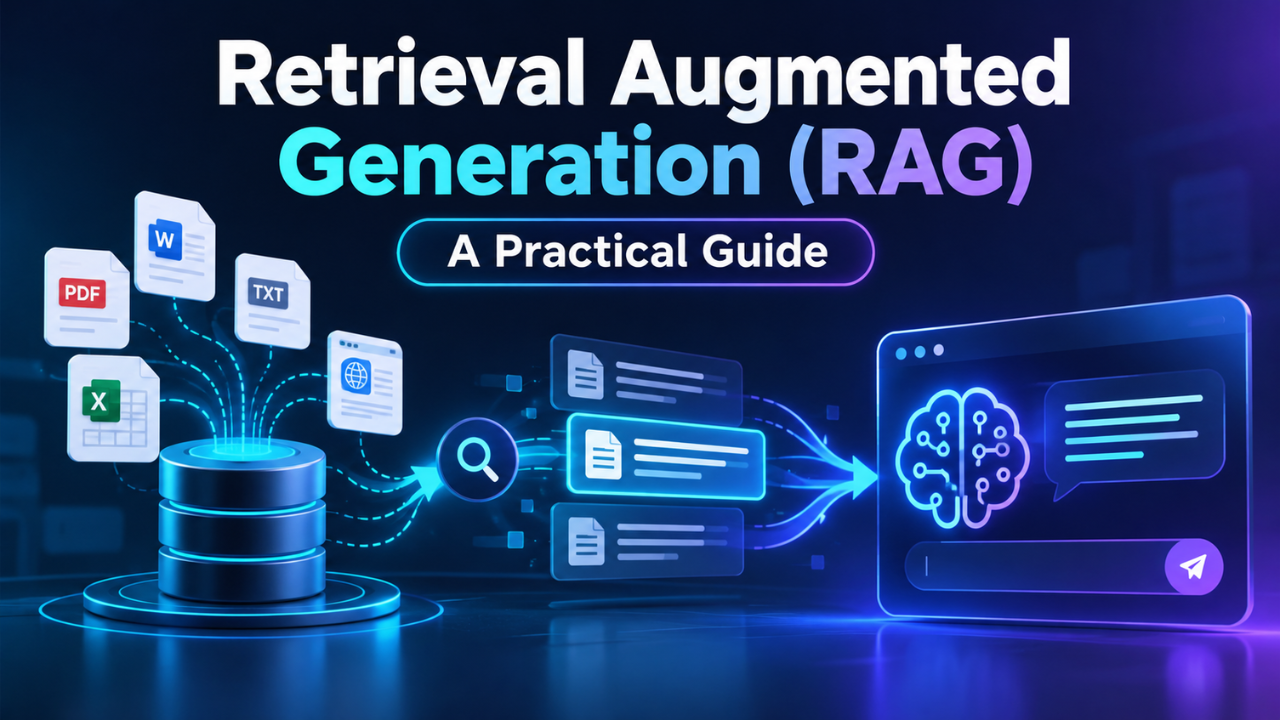
RAG combines information retrieval with text generation. One part of the system finds material relevant to a question. A language model then uses that material to produce a response.
Those sources might live in a document repository, a website, or a database. They don’t have to be public, and retrieval doesn’t have to involve searching the open web.
A model may understand how warranties usually work. Your business, however, may have different terms for refurbished products. RAG gives the model access to those specific terms when someone asks.
Usually, this happens without retraining the model. The application supplies selected information for that request. Updating the sources can therefore change the information available to future answers, provided the retrieval system picks up those changes.
From a Question to a Grounded Answer
Suppose an employee asks, “Can I claim travel expenses for a weekend client visit?”
The system first searches the company’s available information. It might retrieve passages from the expense policy and travel handbook.
Next, the application places those passages alongside the employee’s question in the model’s input. This is the augmentation step: adding useful context to the request.
The model then generates an answer using that context.
The model uses that information to create a relevant answer. A well-designed application can also show links or references so the employee can check the original wording. That’s what a grounded answer means: its claims are supported by the supplied material.
In this example, a useful response would explain the weekend rule, mention any approval requirement, and point to the relevant policy section.
If the policy doesn’t cover weekend visits, the answer should say that clearly. “The available documents don’t specify this” is more helpful than an invented rule.
Why the Search Step Matters So Much
Here’s the thing: a capable language model can still struggle if it receives the wrong information.
A search for “leave” might return annual leave guidance when the employee wanted parental leave. An answer built from those results can sound convincing while missing the question entirely.
Different search methods help with different problems. Keyword search is useful for exact product names, reference numbers, and technical terms. Vector search uses numerical representations called embeddings to find passages with similar meanings, even when the wording differs.
Hybrid search combines keyword and vector search. Some systems also rerank the results, taking another look at which passages best fit the question.
More retrieved text doesn’t automatically produce a better answer. A few relevant passages can be more useful than pages of loosely related material.
Good Answers Start With Useful Documents
It’s tempting to upload every file and expect the system to sort everything out.
Let’s be honest, most shared folders contain old drafts, duplicate policies, unexplained abbreviations, and at least one document called “final_v3_updated.”
Start by deciding which sources deserve to be trusted. Remove obsolete copies, identify the current version, and give documents clear titles. Keep useful details attached, including publication dates, product versions, and links to the originals.
Long documents are usually broken down into smaller parts, known as chunks. This helps the system retrieve focused passages and work within model input limits.
The boundaries matter. Imagine separating “Returns are accepted within 30 days” from the next sentence: “This excludes custom-made products.” Retrieving only the first sentence creates a misleading answer.
Chunking should preserve enough surrounding context to make a passage understandable. Headings, related sentences, and small overlaps between sections can help. There’s no universal chunk size that suits every collection.
Before changing search settings, read a few retrieved passages yourself. If they’re confusing on their own, the model has a difficult starting point.
Where RAG Earns Its Place
RAG is useful when people repeatedly need answers from a body of information that’s hard to navigate.
A support team might use it to find troubleshooting steps across several product manuals. A new employee could ask where to request equipment, without knowing which department owns the process. A sales representative might locate the right technical specification during a customer call.
These are examples of the broader opportunity: reducing the effort between asking a question and finding the material that answers it.
The strongest use cases have reasonably reliable sources and questions those sources can actually resolve.
Sometimes a clearly written FAQ is enough. If everyone asks the same five questions, improving that page may be the quickest fix. RAG becomes more interesting when the questions vary and the relevant information is spread across many documents.
RAG and Fine-Tuning Solve Different Problems
RAG and fine-tuning are often discussed together, but they change different parts of the setup.
Retrieval supplies information when a question is asked. Fine-tuning changes a model through additional training, often to improve its behavior, response format, or performance on a particular task.
For example, you might want answers that consistently follow a specific support format. Fine-tuning could help teach that pattern. You might also need those answers to reflect the latest product documentation. Retrieval can supply it.
The two approaches can work together. A fine-tuned model can still use retrieved passages.
For questions about frequently changing documents, start by checking whether retrieval meets the need before adding training work.
What Can Still Go Wrong
RAG can reduce unsupported answers, but it doesn’t guarantee accuracy.
The system might retrieve an outdated policy, overlook an exception, or combine passages from incompatible product versions. The model can also add claims that the supplied text doesn’t support. Clear instructions about using evidence, handling conflicting sources, and admitting missing information help address these problems.
Privacy needs attention too. A staff member should only retrieve documents they’re authorized to access. Those restrictions belong in the retrieval process, before sensitive content reaches the model.
Retrieved documents can also contain malicious instructions that try to redirect the model. Applications need safeguards that keep document content separate from the instructions controlling the system.
There’s a practical tradeoff as well: searching, processing passages, and generating an answer add work. Longer inputs and additional retrieval steps can increase cost and waiting time.
A useful system balances evidence quality with the speed people need.
How to Tell Whether It’s Working
A smooth demonstration is encouraging. Everyday questions provide a tougher test.
Build a small collection of questions people actually ask. Include straightforward requests, vague wording, questions requiring two documents, and cases where the answer isn’t available.
Evaluate the search and the final response separately. Did retrieval find the material needed to answer? Did the response stay faithful to that material? Did it address the question fully? These checks measure different parts of the system.
Open the citations too. A link to a relevant document doesn’t prove that the document supports every claim in the answer.
Suppose a customer asks about a warranty exclusion. If the search misses the exclusion paragraph, improve retrieval. If the paragraph is supplied but the answer ignores it, examine how the response is generated.
That distinction saves time. You can fix the failing part instead of repeatedly changing everything.
Start Small and Keep the Sources Current
A manageable first project might cover one product range, one department, or one frequently used handbook. Choose a collection someone can review, then test it against real questions.
Give somebody responsibility for the source material. When a policy changes, the searchable content needs to change too. Deleted documents and withdrawn guidance should disappear from future retrieval results. Freshness depends on that maintenance process.
Expand once the smaller system produces useful, checkable answers.
Retrieval augmented generation works best when the documents, search, and responses support each other. Its value comes from helping someone find the right information and understand it with less effort. A good answer should make the next step clearer—and leave the reader able to check where it came from.